Client project · Maritime
Maritime records digitization
220 million ship records, from 1760 to today.
Ctrl+Space Labs is extracting 220 million ship records, many of them handwritten, from scanned pages into structured CSV data, using fine-tuned vision models evaluated against human transcribers, with a bar of more than 98% accuracy on the extracted information.
Maritime organisation · name withheld
- 220Mship records in scope
- 1760earliest records, through to today
- >98%extraction accuracy bar
The challenge
From scanned pages to structured CSV.
Off-the-shelf OCR stops at characters: it turns a scanned page into text. This is a data extraction project — every record is pulled out of the page into the right fields and delivered as CSV rows, ready to query.
Structure, not characters
Each record has to become its own row, with every value in the right column — not a transcript of the page.
Handwriting
Hands, spelling and page layouts change across more than two and a half centuries of records.
Accuracy at scale
Across 220 million records, every value has to be as trustworthy as a human transcriber’s, or the dataset cannot be used.
Method
How the models earn the accuracy bar.
Accuracy is measured, not assumed: models are fine-tuned, scored against people, and only then put to work on the full archive.
- 01
Build the evaluation set
Reference transcriptions define what a correct extraction looks like, field by field.
- 02
Fine-tune the models
Vision models are fine-tuned on the archive’s own handwriting and record formats.
- 03
Evaluate against people
Every model version is scored against human transcribers before it is trusted.
- 04
Extract at scale
Pages run through Gendox Document Digitization into a fixed schema and export as CSV.
Built with Gendox
Page by page, into a fixed schema.
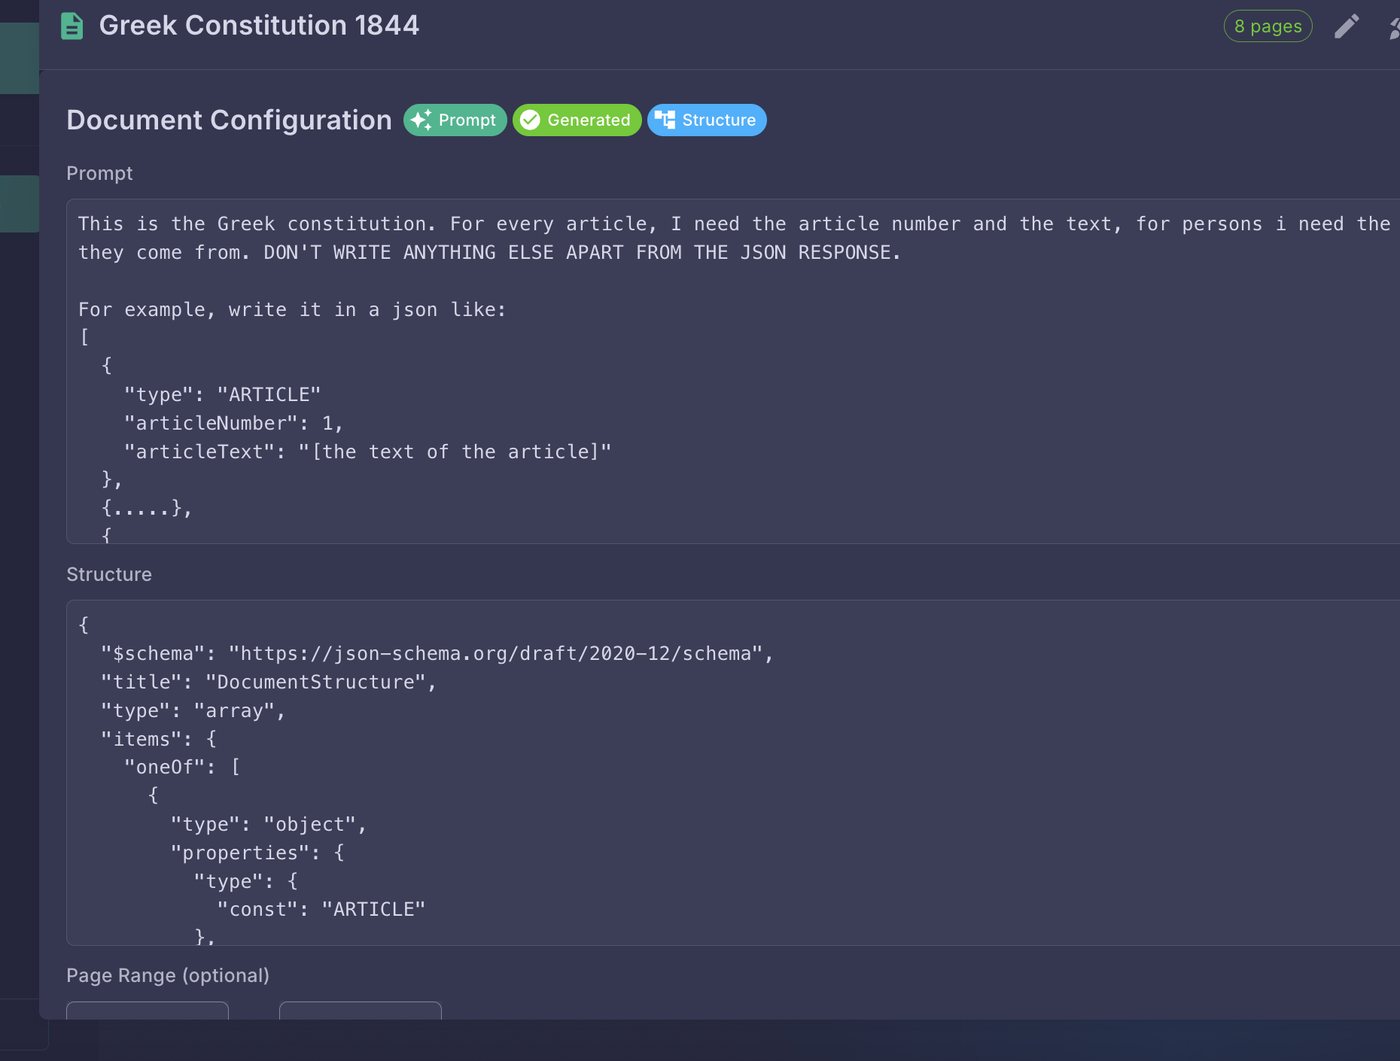
Gendox Document Digitization sends each page to a vision model with a plain-language prompt and a JSON schema, so every record comes back with the same fields — ready to validate, search and export as CSV.
Contact
Get in touch.
Tell us what you are building. We will tell you whether we can help.